
Advanced Settings for Brim Variables
Brim gives you precise control over how variables behave in your project. When you are creating or editing a variable, you can click the “Show Advanced Settings” to find additional options that affect generation behavior, LLM usage, aggregation configuration, and document-level constraints. Here’s how to use each setting.
1. Override LLM Model (if available)
Projects are configured with an LLM model to use by default. You may want to override this for a specific variable because:
- This variable is very complicated, so you want a more capable or reasoning model.
- You want to test outputs from a different model.
Override model
- To require a specific model for this variable, use the dropdown.
- Models must be set up by a Brim Admin to appear here.
- This overrides the "Use Advanced model" option below.
Use Advanced Model
Enable this option if you want Brim to use the most advanced model configured for generating the value of this variable. This can improve accuracy for complex fields but may increase generation time or cost. This defaults to unchecked.
Enable for: nuanced or sensitive variables that require deeper language understanding
Disable for: most variables, most of the time.
2. Prompt Template
Customize the format used to generate instances of your variable. Brim will use this template to guide the LLM to output structured JSON with the abstracted value, raw source text, and confidence level.
Brim variables and dependent variables come with a default prompt template. We recommend using this one because it contains the best practices for variable abstraction.
If your variable is using the default prompt template, you'll see a green "Default Prompt Template" tag. If not, you'll see a link to "see default template". If you click that link, you'll have the option to use the Default Prompt Template for this variable. If you do, don't forget to save your variable.
Warning: Changing the prompt template can have unexpected impact on your downstream data. This is not recommended unless you have prompt engineering experience.
3. Aggregation Prompt Template
This prompt is used when Brim needs to combine multiple instances into a single aggregated value (for one per patient and one per note variables).
Brim variables and dependent variables come with a default aggregation prompt template. We recommend using this one because it contains the best practices for variable abstraction.
If your variable is using the default aggregation prompt template, you'll see a green "Default Prompt Template" tag. If not, you'll see a link to "see default template". If you click that link, you'll have the option to use the Default Aggregation Prompt Template for this variable. If you do, don't forget to save your variable.
Warning: Changing the aggregation prompt template can have unexpected impact on your downstream data. This is not recommended unless you have prompt engineering experience.
4. Index Type
This describes how Brim decides which parts of a note are sent to the LLM. There are two index types:
- Standard: Searches the full note using keyword and semantic matching.
- Prefiltering: Sends only matching lines and their surrounding context to the LLM. This can reduce token use, which is especially helpful for long, repetitive notes.
Standard is the default. Prefiltering trades some sensitivity for speed and efficiency, since lines without matching terms are not sent. Use Prefiltering if you want to reduce token usage. Standard is the better choice for most variables.
For more detail, see Learn more: Using the Variable Index View
Prefiltering options
When you select Prefiltering, you can configure the following:
- Terms to Always Include: Extra search terms for Prefiltering, one per line or comma-separated. These are always kept. Use this for terms the automatic expansion misses.
- Terms to Always Exclude: Terms to remove from the Prefiltering search list, one per line or comma-separated. An exclusion wins over everything, including terms from the variable's own name.
- Surrounding Lines: The number of lines kept immediately before and after each matching line. Defaults to 1.
- Maximum Number of Matching Lines to Send: Caps how many matching lines are sent (choose 1 to 12). Lines are ranked by match density. The default is No Maximum, which sends all matching lines and their surrounding lines.
Previewing Prefiltering
- Click Preview Filter Terms to see the terms Prefiltering will search for.
- Click Preview Index for a note to see what Prefiltering would send for a specific note.
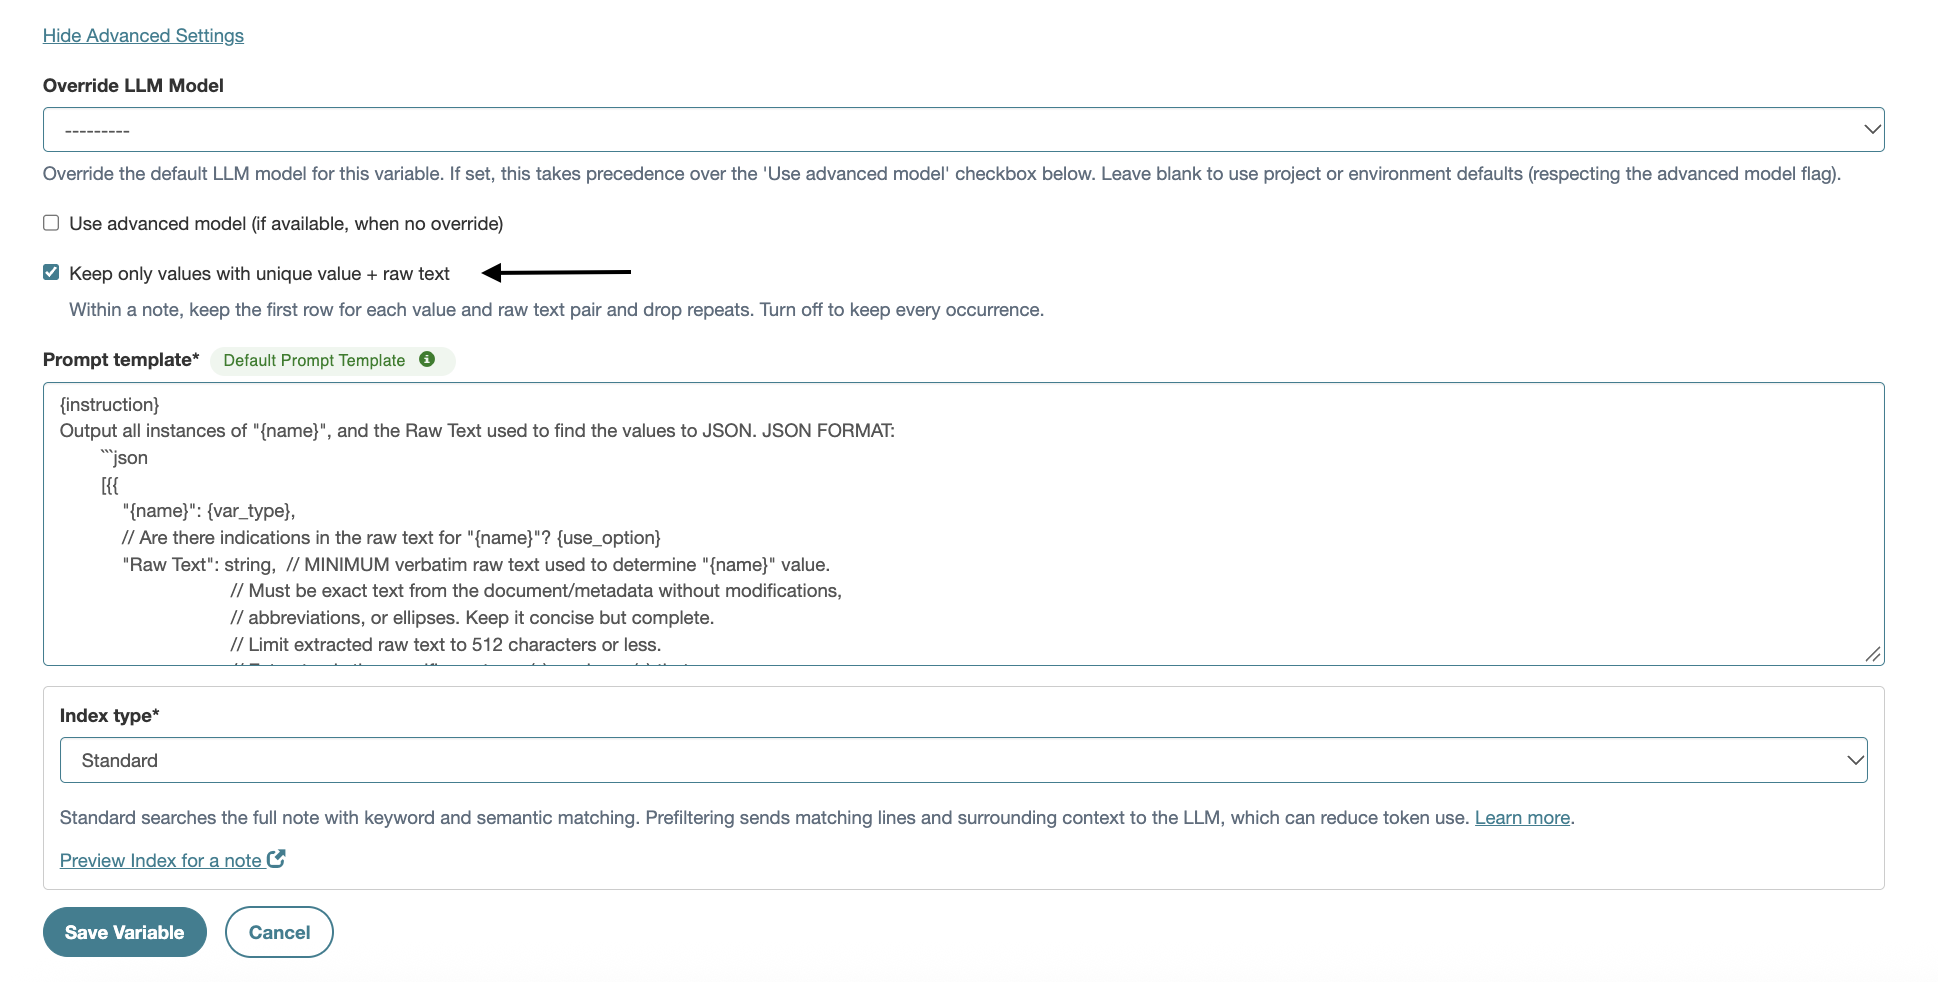
5. Keep Only Values with Unique Value + Raw Text
This setting is available for Many Per Note variables.
When turned on, Brim looks at each value and raw text pair within a note and keeps only the first occurrence of each pair. Repeats are dropped.
When turned off, Brim keeps every occurrence.
Enable for: notes where the same finding is repeated, such as copied-forward text, so you only get one entry per unique value and source text.
Disable for: variables where you need every occurrence.
Saving Your Changes
Once you've adjusted these settings, click “Save Variable” to apply changes and return to your variable list.